TechEnded
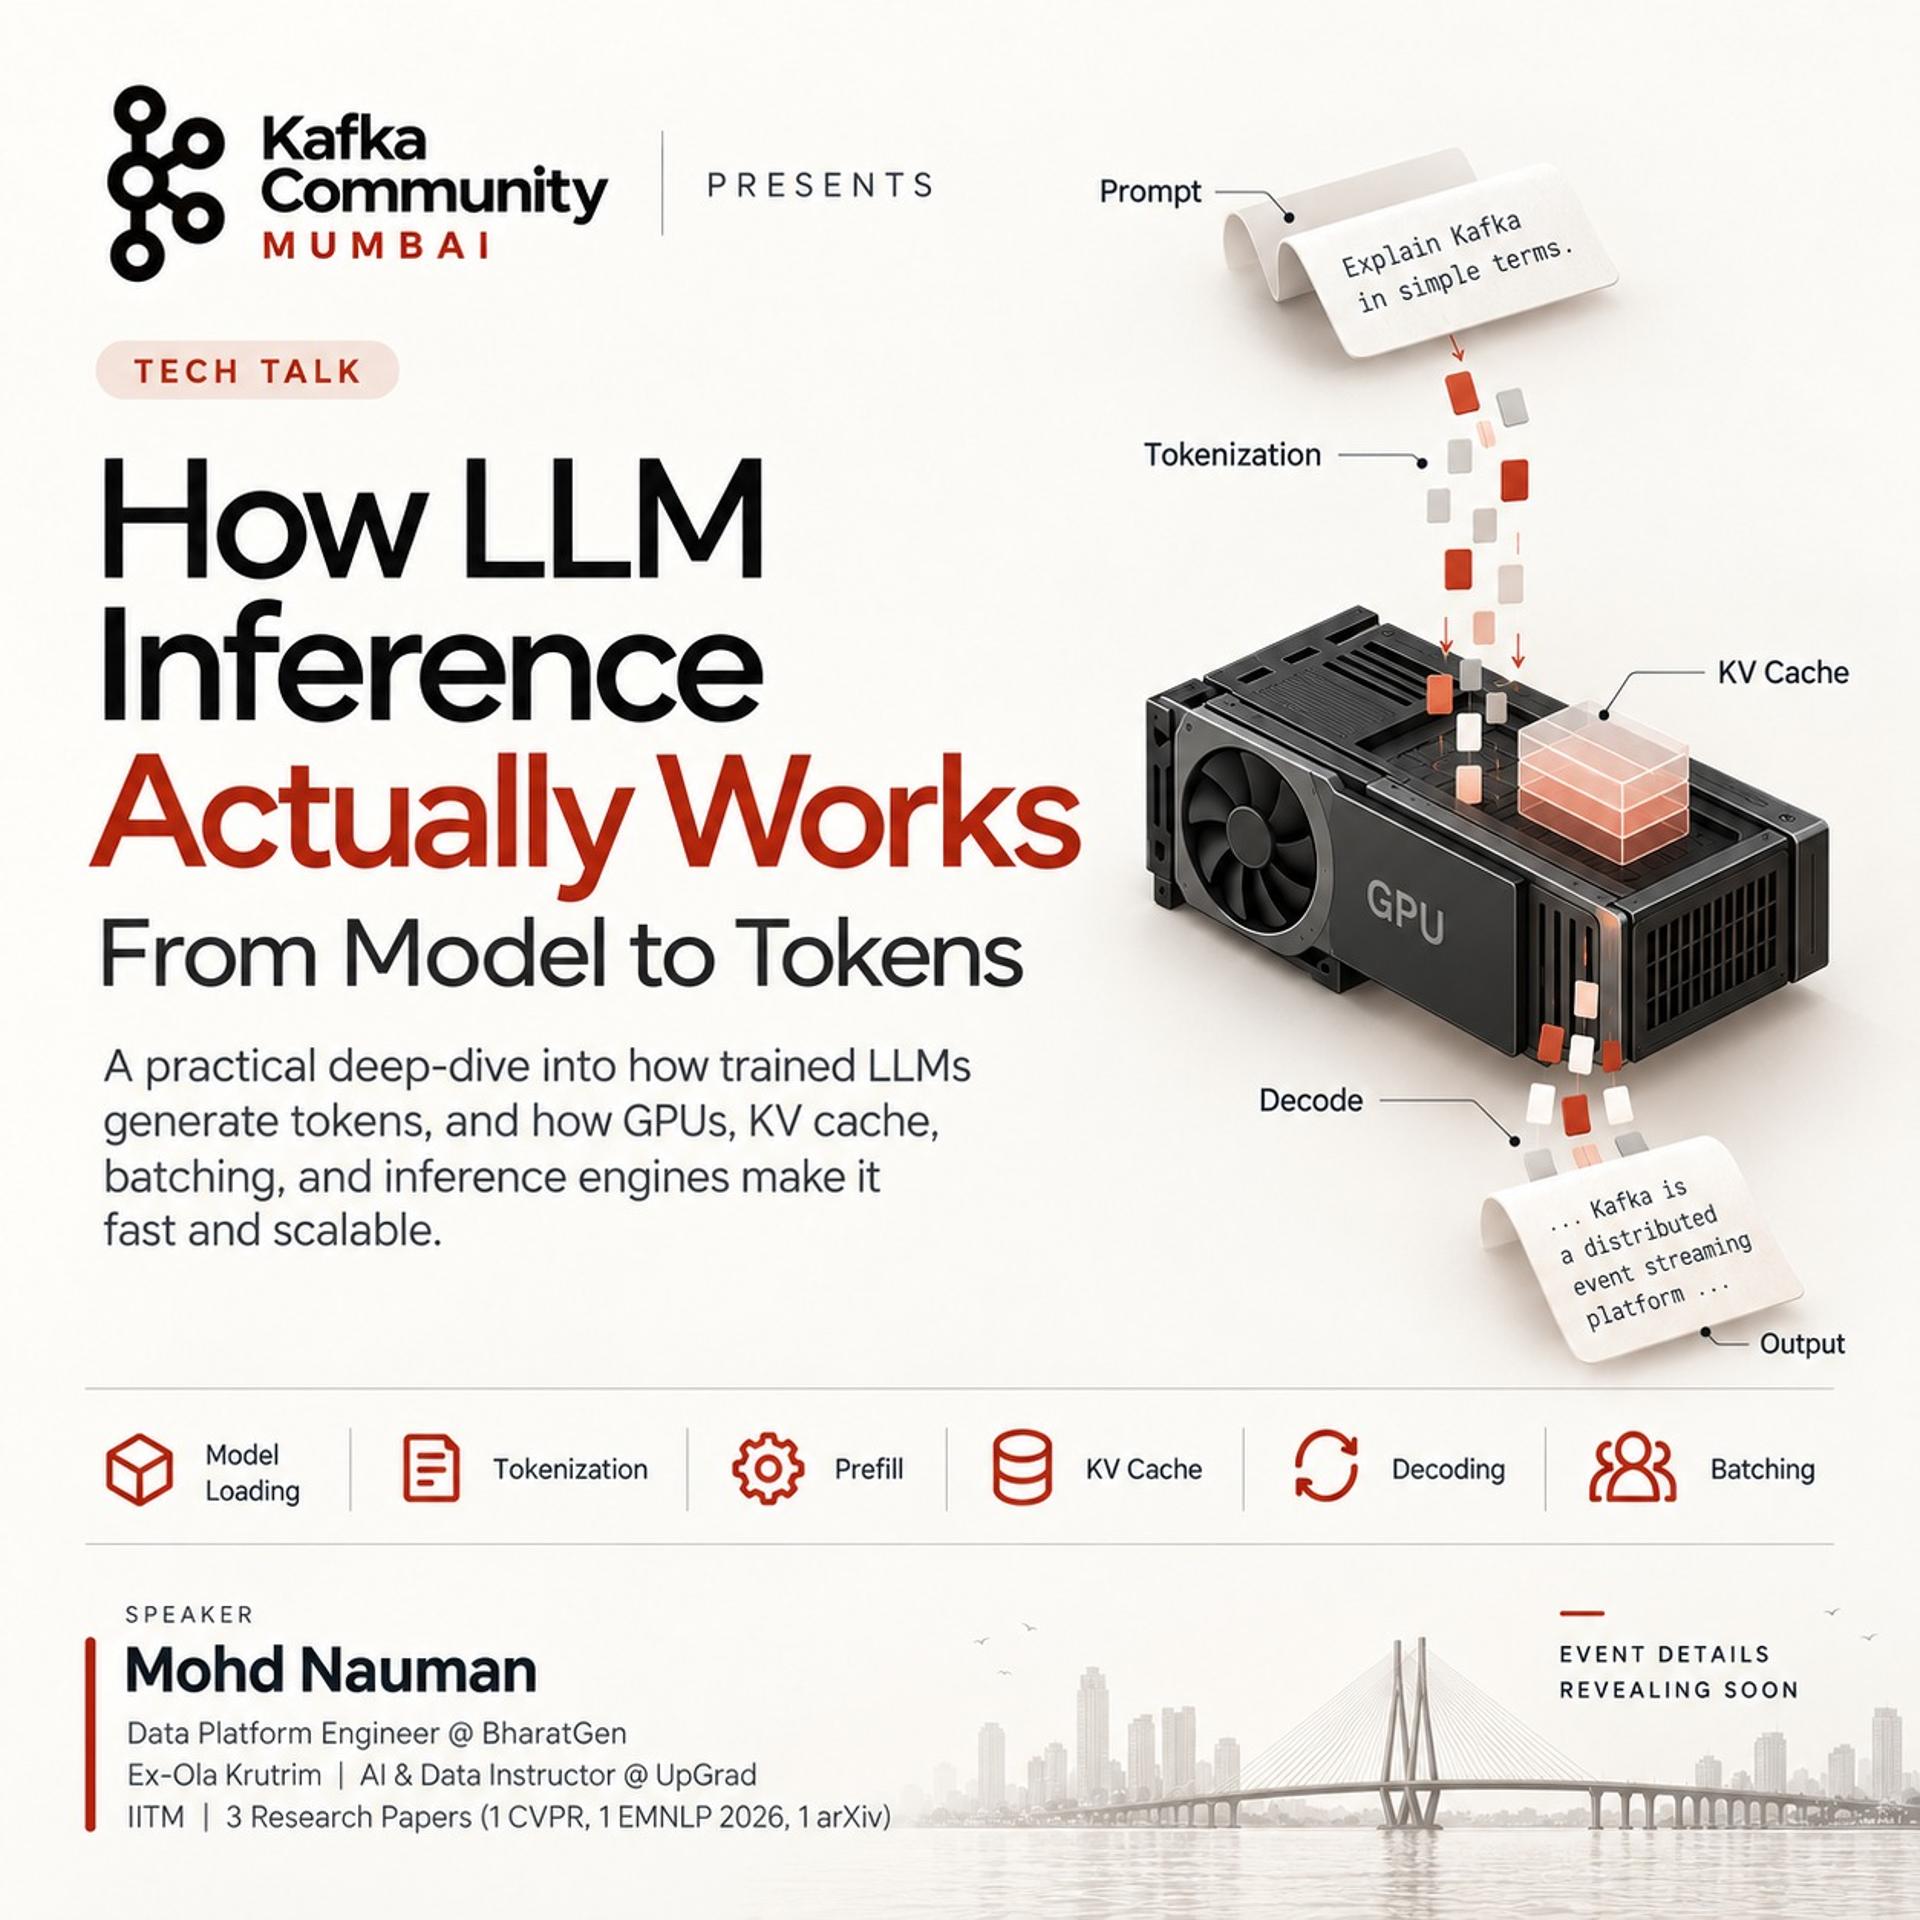
Inside LLM Inference: From Model Weights to Tokens at Scale
Ever wondered what actually happens after you hit Send on ChatGPT?
OCT
17
Saturday, 17 October 2026
10:00 AM – 11:00 AM IST
ATLAS SkillTech University - Building 2, BKC51, Bandra Kurla Complex
ATLAS SkillTech University - Building 2, BKC51, Mumbai, Maharashtra
Open in maps About
Ever wondered what actually happens after you hit Send on ChatGPT?
We talk a lot about training LLMs, building AI agents, and using APIs. But how does a trained model actually generate tokens? What happens inside the GPU? And how do inference engines serve thousands of requests efficiently?
In this session, we'll break down LLM inference from the ground up-starting with model weights and token generation, then exploring the engineering challenges of running LLMs in production.
We'll cover:
From Model to Inference: How a trained model is loaded and generates its first token.
Inside Token Generation: Embeddings, attention, prefill, decoding, and autoregressive generation.
KV Cache: Why it matters and how it affects memory and performance.
GPU Memory & Compute: What limits inference speed and how model size and context length affect resource requirements.
Scaling Inference: Batching, continuous batching, and how engines like vLLM serve concurrent requests.
We'll also explore practical trade-offs between latency, throughput, memory utilization, and cost.
Who should attend?
Developers, AI/ML engineers, students, and anyone curious about what happens beyond an LLM API call.
No deep ML background required. A basic understanding of programming is enough.
Join us to understand not just how to call an LLM, but how to actually run one efficiently.
More Tech
2:00 PM – 5:00 PM
Luminaire 2.0 - Gaurav Sen
Mukesh Patel School of Technology Management & Engineering, Mumbai
7:30 PM – 9:30 PM
Building Mumbai’s AI Talent | Launch of the Google Mumbai Data Challenge
Mumbai, India
10:00 AM – 1:00 PM
Structuring the AI Way
https://luma.com/event/evt-SkxxqDeiqU1N3hD
10:00 AM – 1:00 PM
Hands-on Workshop - On-device AI with Gemma 4
Bandra / BKC